Matching is the single biggest bottleneck on a graduate desk. It decides how fast a shortlist goes out, whether a database of registered graduates earns anything, and how much of a consultant's week disappears into search. Below: what manual matching costs, how AI matching works in both directions, finding live roles for your graduates and finding graduates in your own database for live roles, and how to build the business case on your own numbers.
Why is matching the bottleneck on a graduate desk?
Because on most desks, matching still happens in a consultant's head. A Boolean search on LinkedIn, a keyword filter, and a memory of what the candidate said they wanted three weeks ago. The consultant is manually filtering thousands of options against each other, and both sides of that comparison are dense: job adverts full of requirements on one side; CVs, preference notes and call write-ups on the other. No one can hold that in working memory, so every manual match is a compromise between speed and quality.
Graduate recruitment makes it harder still. A graduate CV carries little work history, so the real signal sits in degree, interests and what came out in conversation. And "entry level" has no standard definition: job boards flag it inconsistently, part of the market hides in a salary band rather than under a graduate label, and much of a typical graduate desk's work is really the two-to-five-year bracket rather than fresh graduates.
What does slow matching actually cost an agency?
Three costs, none of which show up on a dashboard. First, the dormant database: thousands of registered graduates set against a much smaller number of live roles, most of whom never hear from the agency again after registration, and some of whom quietly register with a competitor. Second, missed timing: entry-level roles open and close fast, so a role that went live on Monday can be gone before anyone thinks to check the database against it. Third, slow ramp: judging candidate-to-role fit well is the skill that takes a junior consultant months to build, which caps how quickly a new hire starts producing.
There is a fourth cost that compounds: reputation. Every weakly matched CV an agency sends teaches an employer to skim its emails. Every strongly matched one does the opposite.
How does AI matching handle a graduate candidate?
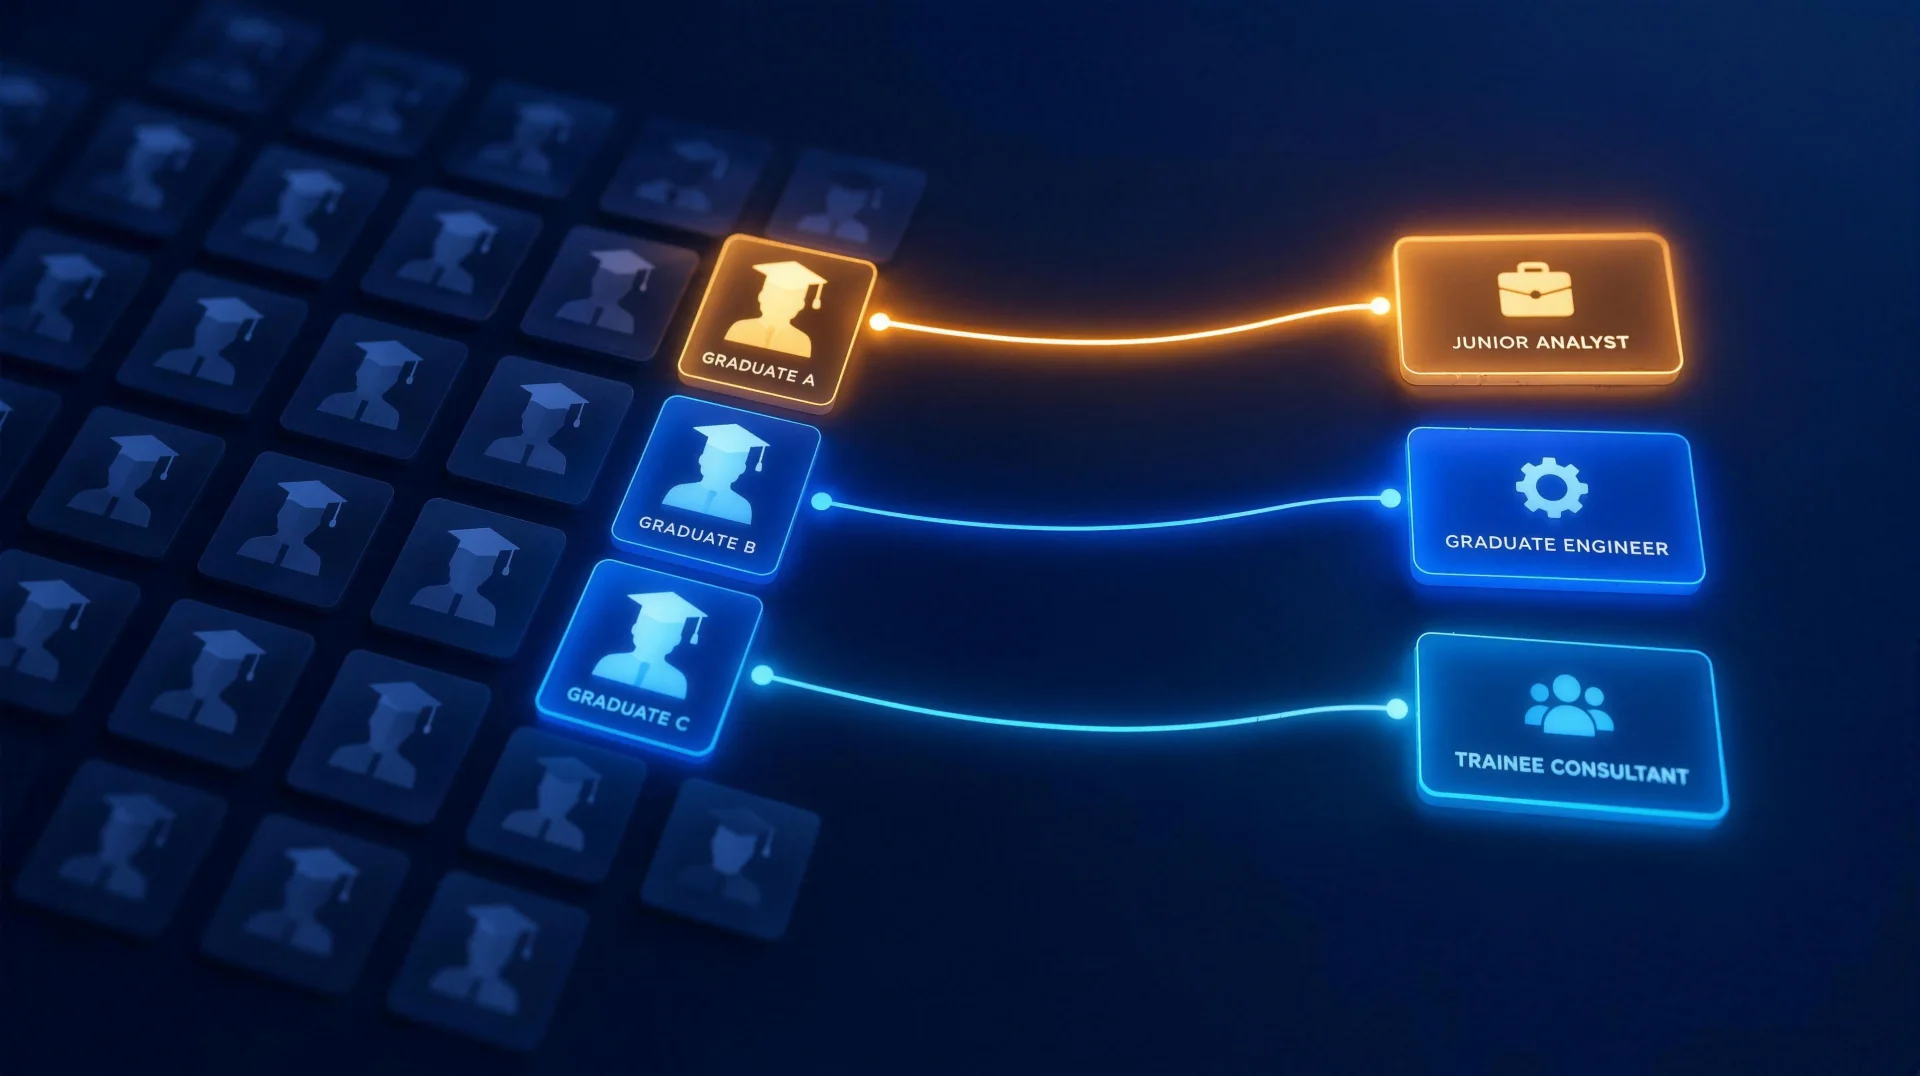
Upload a graduate's CV, notes and preferences, and JobVantage returns a ranked shortlist of live, relevant roles with the reasoning written out for each one. The roles are not limited to the vacancies your clients bring you: JobVantage supplies the role side itself, thousands of live roles pulled from multiple online sources, so every graduate is matched against the whole live market, not just the desk's own book. A sequence of filters then narrows them: deterministic rules on location, experience and salary band first, then AI scoring of what survives, down to a shortlist of roughly 30 to 100 roles that genuinely fit. The more information the system has on the candidate, the better the match, so notes and preferences are not optional extras; they are fuel.
The consultant stays the judge. The shortlist shows why each role made the list, and the consultant decides which ones are worth putting their reputation behind. For the roles they pick, the same workflow finds the people worth contacting at that employer, whether hiring manager, HR, talent acquisition or whoever posted the role, enriches them with contact details, and drafts the outreach using the full context of why this graduate fits this role. It can then run as a multi-step email sequence from the consultant's own mailbox or a managed one. Recruiters call this speccing; done with genuinely matched candidates, it reads less like a cold pitch and more like useful information, which is why it converted at 2x in partner testing.
How does the same matching work a live role?
In reverse, against your own database. Take a live role, from a client or spotted new on the market, and the same staged pipeline ranks the graduates already registered with you, with the same written reasoning. Every new role becomes two things at once: a re-engagement message to graduates who registered months ago, built on a specific opportunity rather than a newsletter, and a BD conversation with the employer, backed by named candidates who actually fit. The database stops being a liability you feel guilty about and starts being the desk's raw material.
How do you build the business case?
With five numbers, all yours, all conservative. How many roles from a shortlist would a consultant actually spec into. How many people they contact per company. How many candidate runs a month the desk would do. Your honest outreach-to-placement ratio. Your average placement fee. Multiply through and you have the expected return before counting any time saved, and before counting the compounding effect of better-matched outreach on reply rates. The habit that makes the numbers work is small: a consultant giving the shortlist 15 to 20 minutes a day.
What does this mean for a graduate desk?
The argument is simple. A graduate desk already owns everything it needs to place more people: registered graduates, consultant judgment and client relationships. What it lacks is the capacity to compare thousands of dense documents in both directions, and that is exactly the part a machine should do. AI matching does the comparing; the consultant keeps the judgment, the relationship and the fee.
In partner testing in 2026, AI matching meant 24x less time on candidate shortlisting, 17 minutes from CV upload to sent spec, and 2x higher conversion on speccing outreach.
JobVantage is AI market mapping and outreach for recruiters. If you run a graduate desk, the fastest way to judge the matching is on your own candidates: request a run and we will do it with you on the call.
Frequently asked questions
Does JobVantage replace our ATS or CRM?
No. It is an overlay that sits on top of your existing ATS or CRM. Nothing migrates; your system of record stays where it is.
Is the matching one-size-fits-all?
No, and this is where most matching tools fail. Desks differ by sector, by what titles mean in their niche, and by which companies they will place into. JobVantage is configured per agency at onboarding and keeps tailoring as you use it.
Why not just run a large language model over everything?
Cost. Brute-force AI matching over every detail of every candidate and role would cost tens of pounds per candidate. A staged pipeline, cheap filters first and AI reasoning only on what survives, delivers the quality at a price that works at desk scale.
Does it only work for fresh graduates?
No. Filters run on experience, salary band, geography and sector, so the two-to-five-year bracket is covered by the same pipeline.